Card sorting is the standard way to find out how people actually group content, but recruiting twenty participants usually costs a few weeks of calendar time.
On smaller projects that’s enough friction that the step just gets skipped.
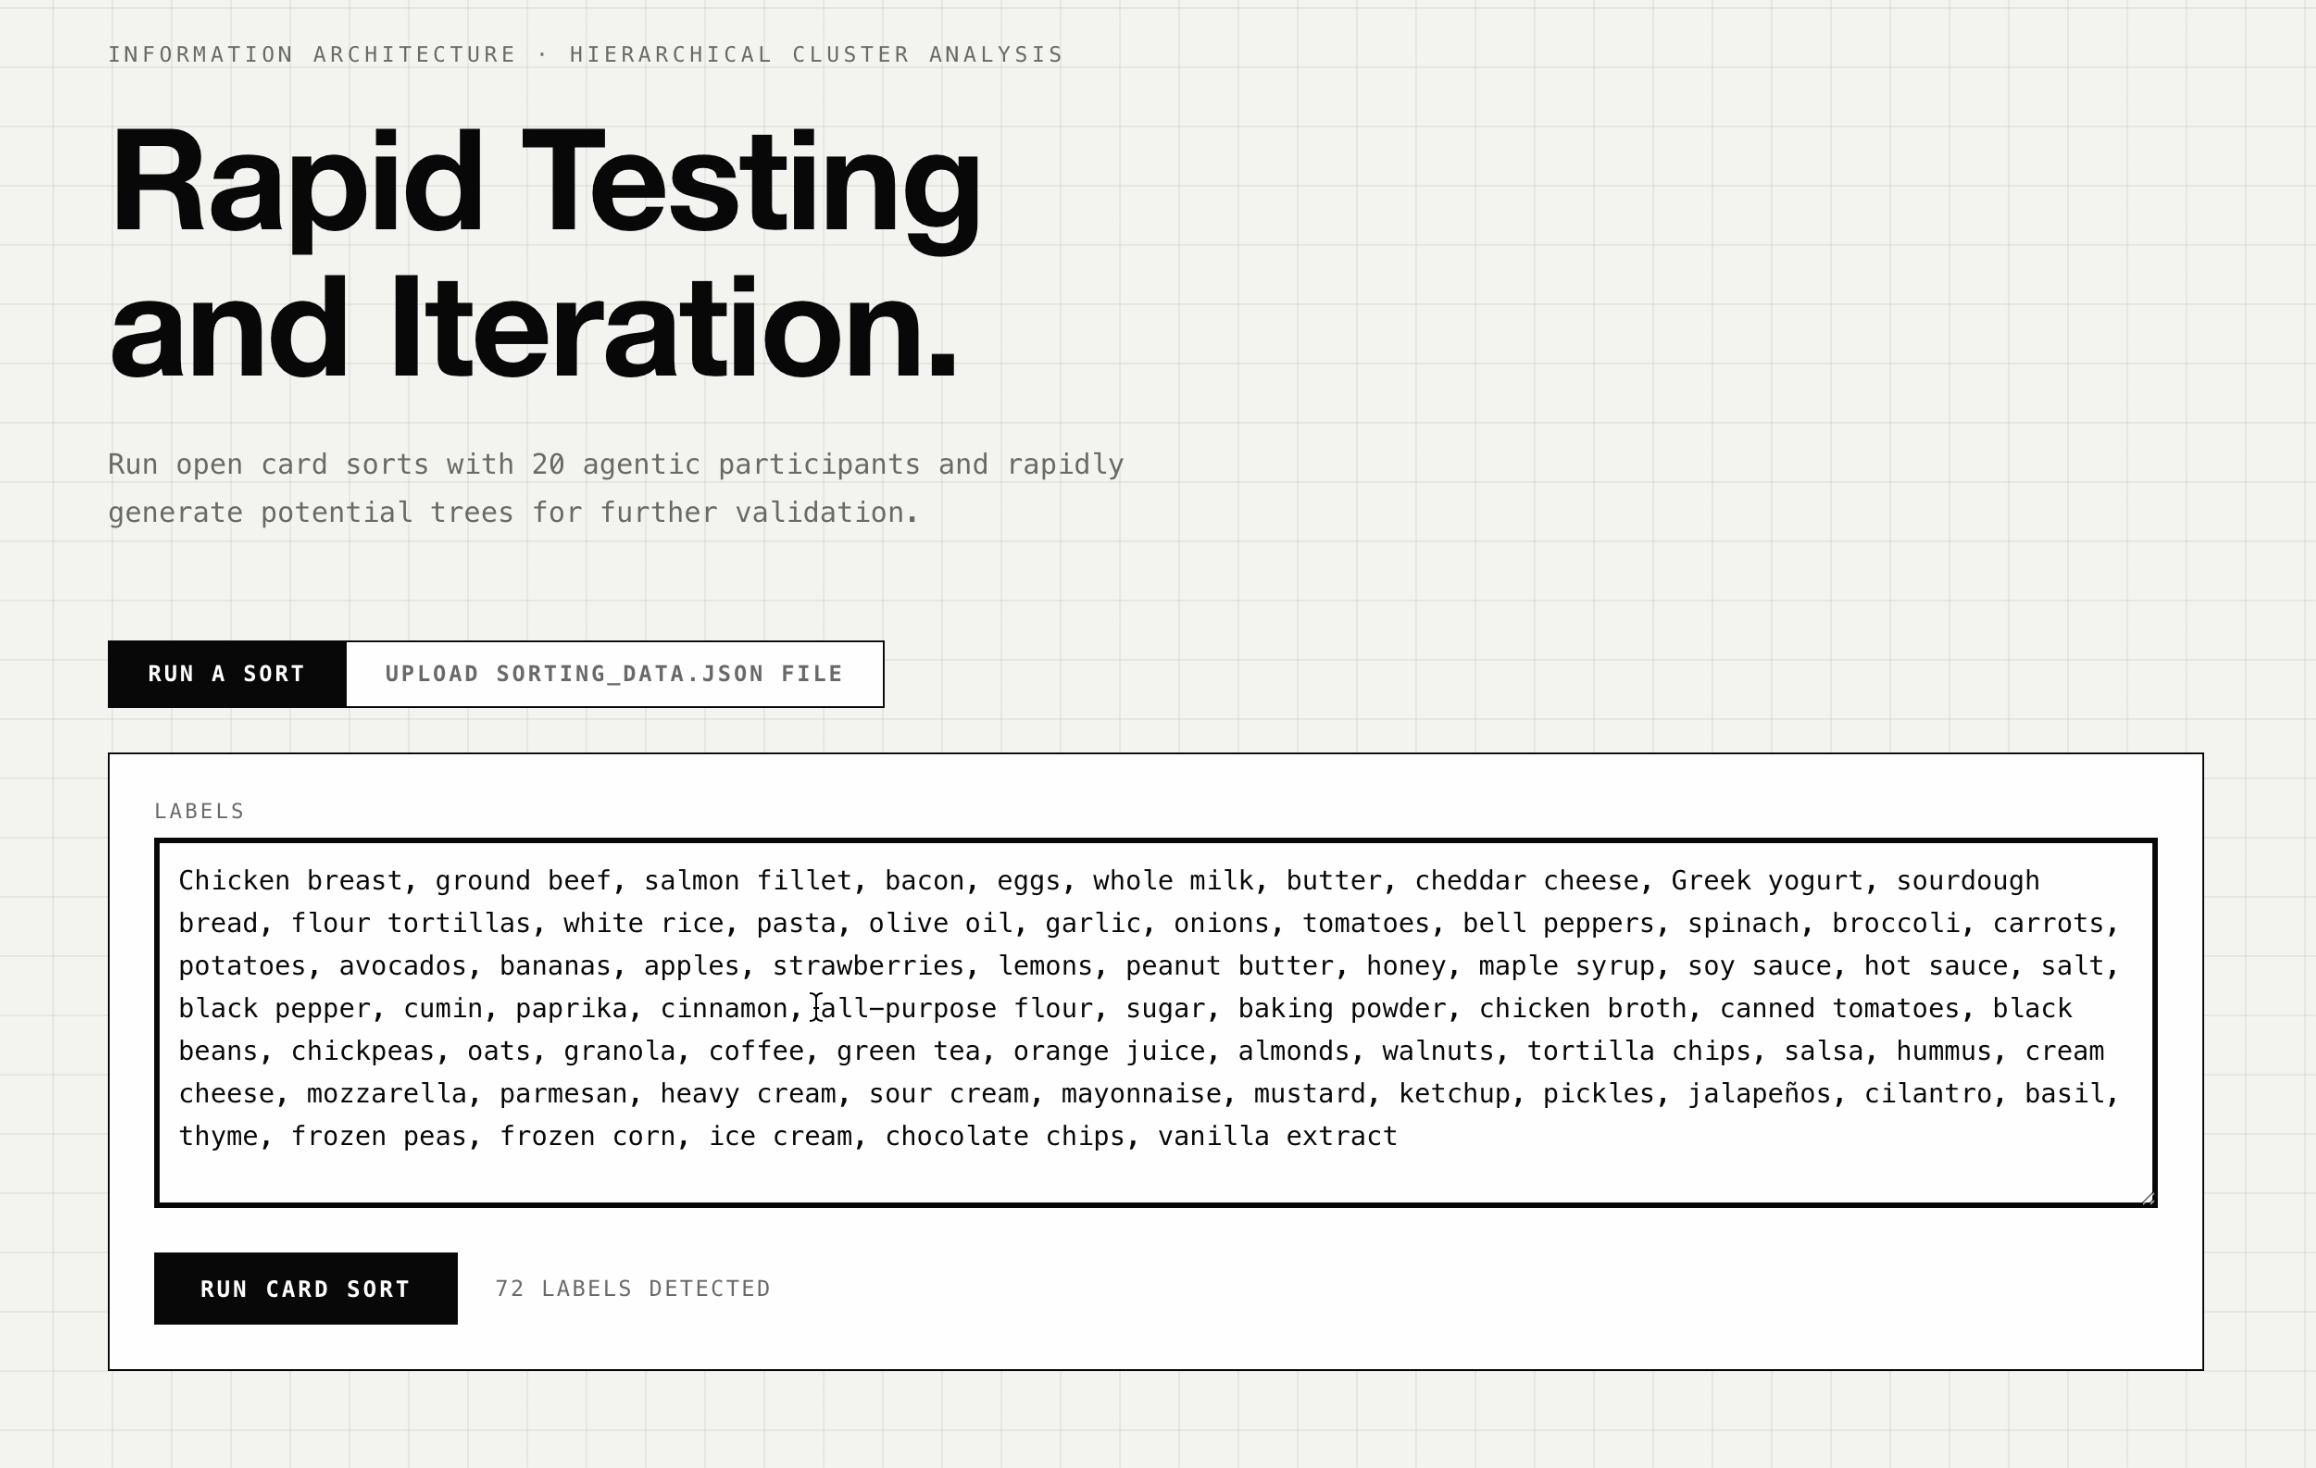
I wanted to know whether an LLM could stand in for those participants well enough to produce a rough first-draft information architecture in an afternoon, so I built the pipeline rather than guessing at the answer.
The setup is two apps in a monorepo, with a FastAPI backend running the agents and doing the clustering through scipy, while an Astro frontend with React islands handles the form and the charts.
You paste a list of labels into a textarea and watch twenty agents finish one at a time.
What comes out is a dendrogram, a similarity heatmap, and a table of clusters you can have named for you.
Why open card sorts are hard to analyze
In a closed card sort you hand participants a set of categories you’ve already decided on, which is useful for validating a structure but useless for discovering one.
An open sort lets each participant invent their own groups and name them however they like, so it tells you far more about how people actually think.
It also means twenty participants hand you twenty different vocabularies for what might be the same underlying structure.
The established way around that is to throw the group names away entirely and count co-occurrence instead, asking only how often each pair of cards ended up together regardless of what anyone called the pile.
That gives you a matrix of pairwise similarity scores, and once you’ve got a matrix you can run hierarchical cluster analysis over it.
The output is a dendrogram, the tree diagram showing which cards merge with which and at what distance.
None of this is new, and I’d point anyone starting out at Donna Spencer’s Card Sorting: Designing Usable Categories, or at OptimalSort if you want to run one with actual humans.
How the twenty agents work
Each of the twenty agents gets a distinct persona in its system prompt, and since there are exactly twenty personas in the list, every run uses each one once rather than sampling with replacement.
I wrote the personas to vary on the thing that actually matters for a card sort, which is the axis someone organizes along.
A librarian sorting by taxonomy sits alongside a developer sorting by technical architecture and a psychology student sorting by cognitive load.
PERSONAS = [
    "a 28-year-old software developer who thinks in terms of technical architecture",
    "a 45-year-old marketing manager who groups things by business function",
    "a 62-year-old retired teacher who organizes by familiarity and simplicity",
    "a 60-year-old librarian who organizes by taxonomy and classification systems",
    "a 21-year-old psychology student who thinks about cognitive load and mental models",
    # ...fifteen more
]
Age and job title are doing less work here than the clause after them.
If I rewrote the list today I might just drop the demographics and keep only the organizing principle, since that’s the part actually changing the output.
Twenty isn’t an arbitrary number either, because Tullis and Wood’s 2004 study on card sort sample sizes found that around twenty participants gets you a correlation of roughly 0.90 with the full set. That’s why most practitioners stop somewhere in the fifteen to twenty range. [link: Tullis and Wood 2004, card sort sample sizes]
Every agent returns its bins through structured output rather than free text, using with_structured_output against a small Pydantic model, so I never have to parse a response and the shape is guaranteed before it reaches my code.
Streaming run completion
The sort endpoint returns Server-Sent Events rather than a single JSON response, because twenty concurrent agents take long enough that an undifferentiated spinner is a genuinely bad experience.
Since as_completed yields in finish order rather than launch order, a progress event fires the moment each agent returns. The interface fills in one participant at a time, so you can see the run is alive.
The terminal complete event carries the whole summary object with all twenty agents’ bins in it, so the client has everything it needs the moment the stream closes. It’s a nice pattern and I’ll be reaching for it again!
From co-occurrence to the dendrogram
The analysis walks every agent’s bins, and for each bin it increments a counter for every pair of cards sitting in it, which builds up a symmetric co-occurrence matrix across the whole study.
for bin_indices in bins_labels:
    for i in range(len(bin_indices)):
        for j in range(i + 1, len(bin_indices)):
            a, b = bin_indices[i], bin_indices[j]
            cooccurrence[a][b] += 1
            cooccurrence[b][a] += 1

similarity = cooccurrence / n_agents
np.fill_diagonal(similarity, 1.0)
Dividing by the agent count turns raw counts into a similarity score between zero and one.
A pair scoring 0.85 means seventeen of the twenty agents grouped those two cards together.
From there it’s standard scipy, converting similarity to distance with 1 - similarity, condensing with squareform, then running linkage for the tree and fcluster to cut it at a chosen number of clusters.
The heatmap is worth the extra step of reordering rows and columns by the dendrogram’s leaf order.
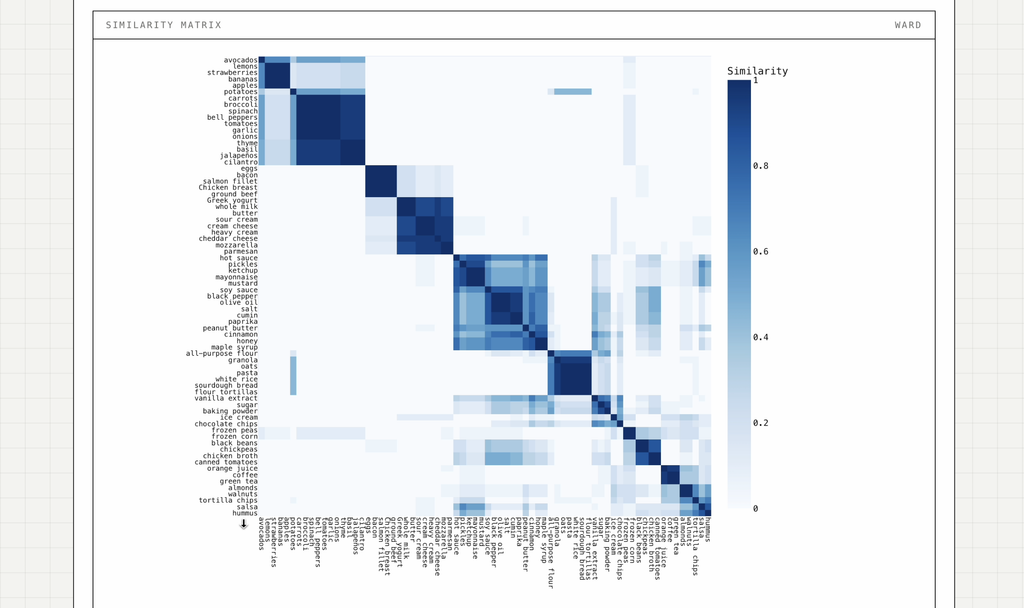
An unordered similarity matrix is visual noise, while an ordered one puts the clusters on the diagonal as solid blocks you can read at a glance!
I defaulted the linkage method to ward because it minimizes within-cluster variance and tends to give evenly sized groups, which is what you want when the output is going to become navigation.
Average, complete, and single are all exposed in the interface, since ward isn’t always the right call.
Breaking out the clustering step
The analysis is split across three endpoints rather than one, with /api/matrix building the dendrogram and heatmap, /api/clusters cutting the tree at a chosen k, and /api/cluster-names naming whatever came out.
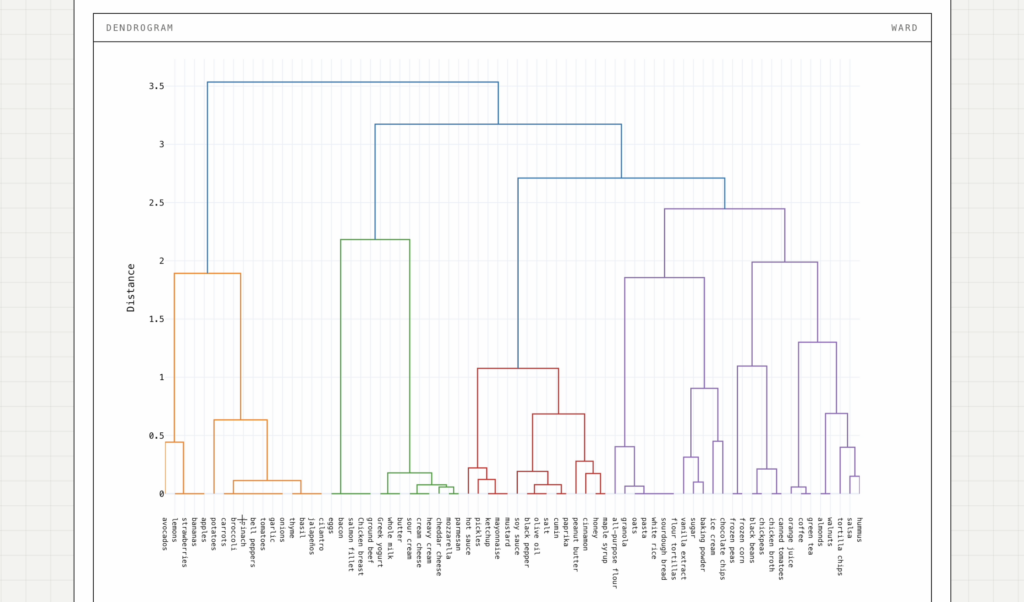
I split them this way because picking a cluster count before you’ve looked at the dendrogram doesn’t make sense. The whole point of the tree is that the big vertical gaps in it tell you where the natural cuts are.
So the matrix view is deliberately independent of k, and you look at it first, then choose a number, then re-cut as many times as you want.
The cost of that split is that both endpoints rebuild the similarity matrix from the uploaded summary, so the work gets done twice. On a 75 card deck that’s a few milliseconds and not worth caching yet.
Naming is its own endpoint for a plainer reason, which is that it costs an API call and may not be desired. Often this step requires more human cognition and interpretation.
JSON vs database
The two halves of the app are connected by a single JSON summary and nothing else, which you can either hand straight from the sort step to the analysis step in memory, or download and upload again later.
I went with a file instead of a database because a card sort study is a one-off, and the artifact worth keeping is the raw participant data rather than the derived clusters. A 95 KB JSON file drops into a repo and diffs cleanly against the next run.
What that costs me is run history, so there’s no way to open the app and compare two studies side by side. If I ever wanted that, the file would stop being enough.
Credit and caveats
The obvious objection to this whole experiment is that synthetic participants can’t tell you how humans group things, only how a language model predicts humans would group things, and those aren’t the same claim at all.
That said, I don’t think that makes the output worthless, because a first-draft IA has to come from somewhere and the usual alternative is one person’s intuition rather than a real study. That’s a lower bar than twenty simulated sorts clear pretty comfortably.
My honest position is that this is a supplement and a starting point rather than a replacement. I’d use it to generate candidate trees worth testing, not to sign off on a structure.
There’s a statistical caveat worth flagging too, which is that ward linkage assumes Euclidean distance and 1 - similarity from a co-occurrence matrix isn’t strictly that.
Ward is a pragmatic default here rather than a correct one, and average linkage is the more defensible choice if you care.
What’s next
The thing I haven’t done, and the thing that would actually settle whether any of this is useful, is run the same 75 card deck past twenty real people and compare the two dendrograms.
Without that comparison I’ve got a tool producing confident looking output with no way to know how far off it is, and every number in this post describes the simulation rather than the thing it’s simulating.
If you’ve run a real card sort recently and would be willing to let me put your deck through this to compare the results, I’d genuinely love to hear from you, since that comparison is the one piece I can’t generate myself!